Oral presentation at the EUROPIN Summer School in Drug Design, summarizing our work on understanding and improving the generalization of machine learning models in chemical space — covering how out-of-distribution data should be defined for molecular property prediction, the limits of in-distribution-based model selection, and practical recommendations for bioactivity and ADMET tasks.
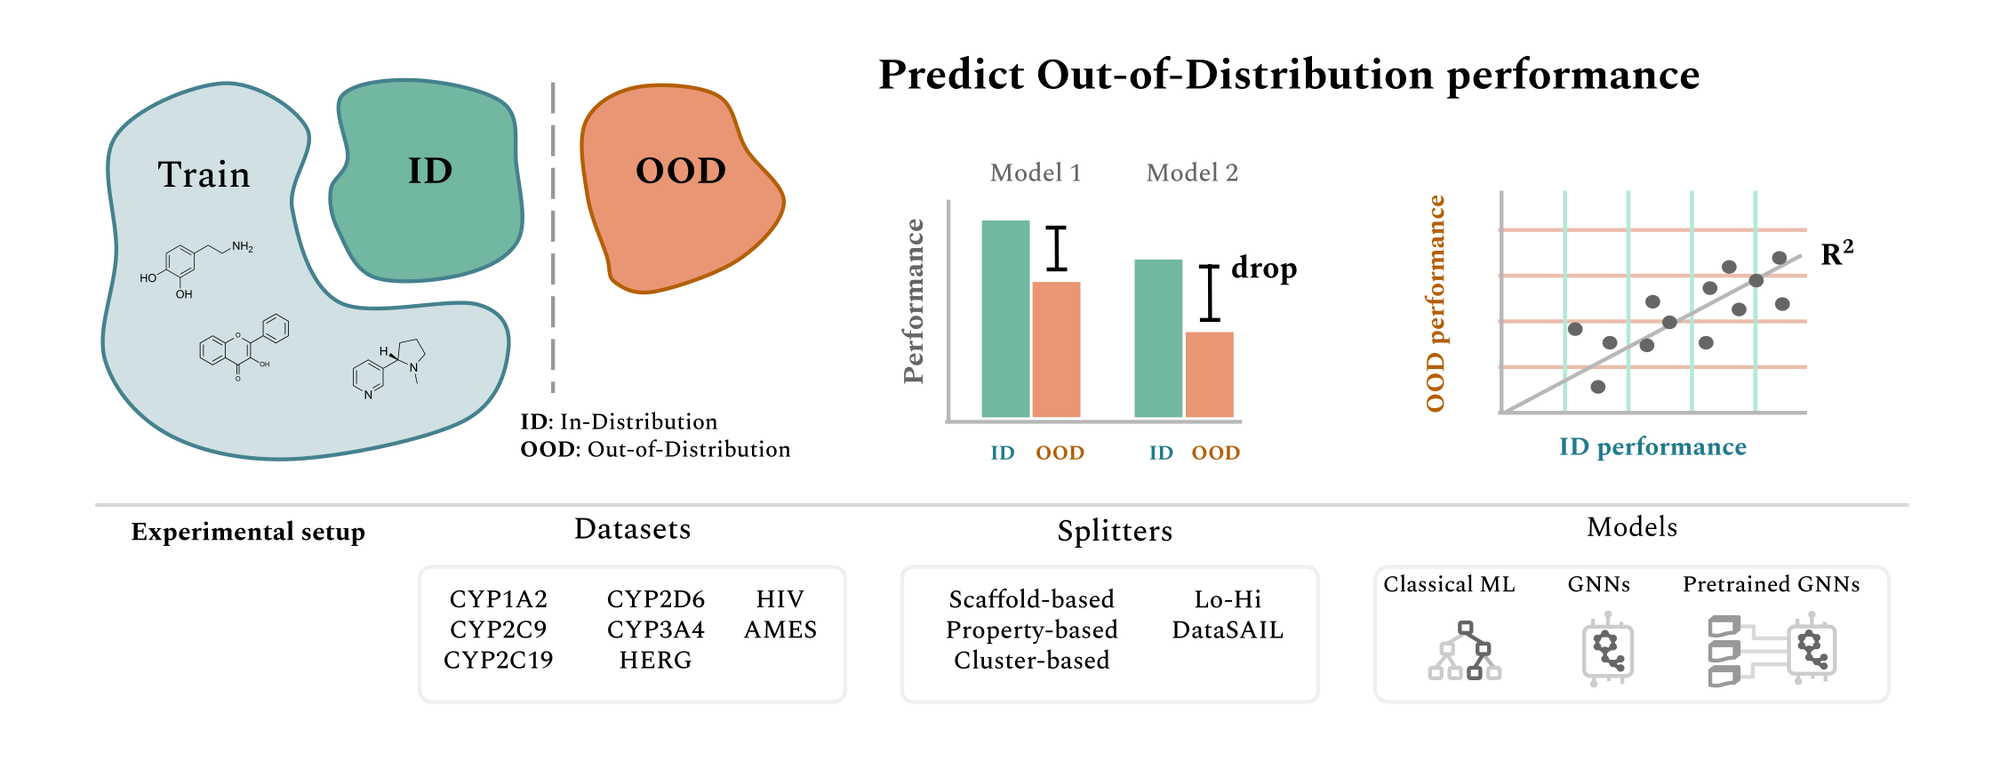
ALineMol overview: a training set with in-distribution and out-of-distribution test molecules; bar charts showing the performance drop from ID to OOD for two models; a scatter of OOD against ID performance; and the experimental setup of datasets, splitters and models.
ALineMol in one picture: molecules are split into in-distribution (ID) and out-of-distribution (OOD) test sets, models are compared on their ID-to-OOD performance drop, and we ask how well ID performance predicts OOD performance. Evaluated on eight datasets (CYP isoforms, hERG, HIV, AMES), ten splitters (scaffold-, property- and cluster-based, Lo-Hi, DataSAIL) and classical ML, GNN and pretrained-GNN models.

Authors: Hosein Fooladi and Johannes Kirchmair.

Updated: